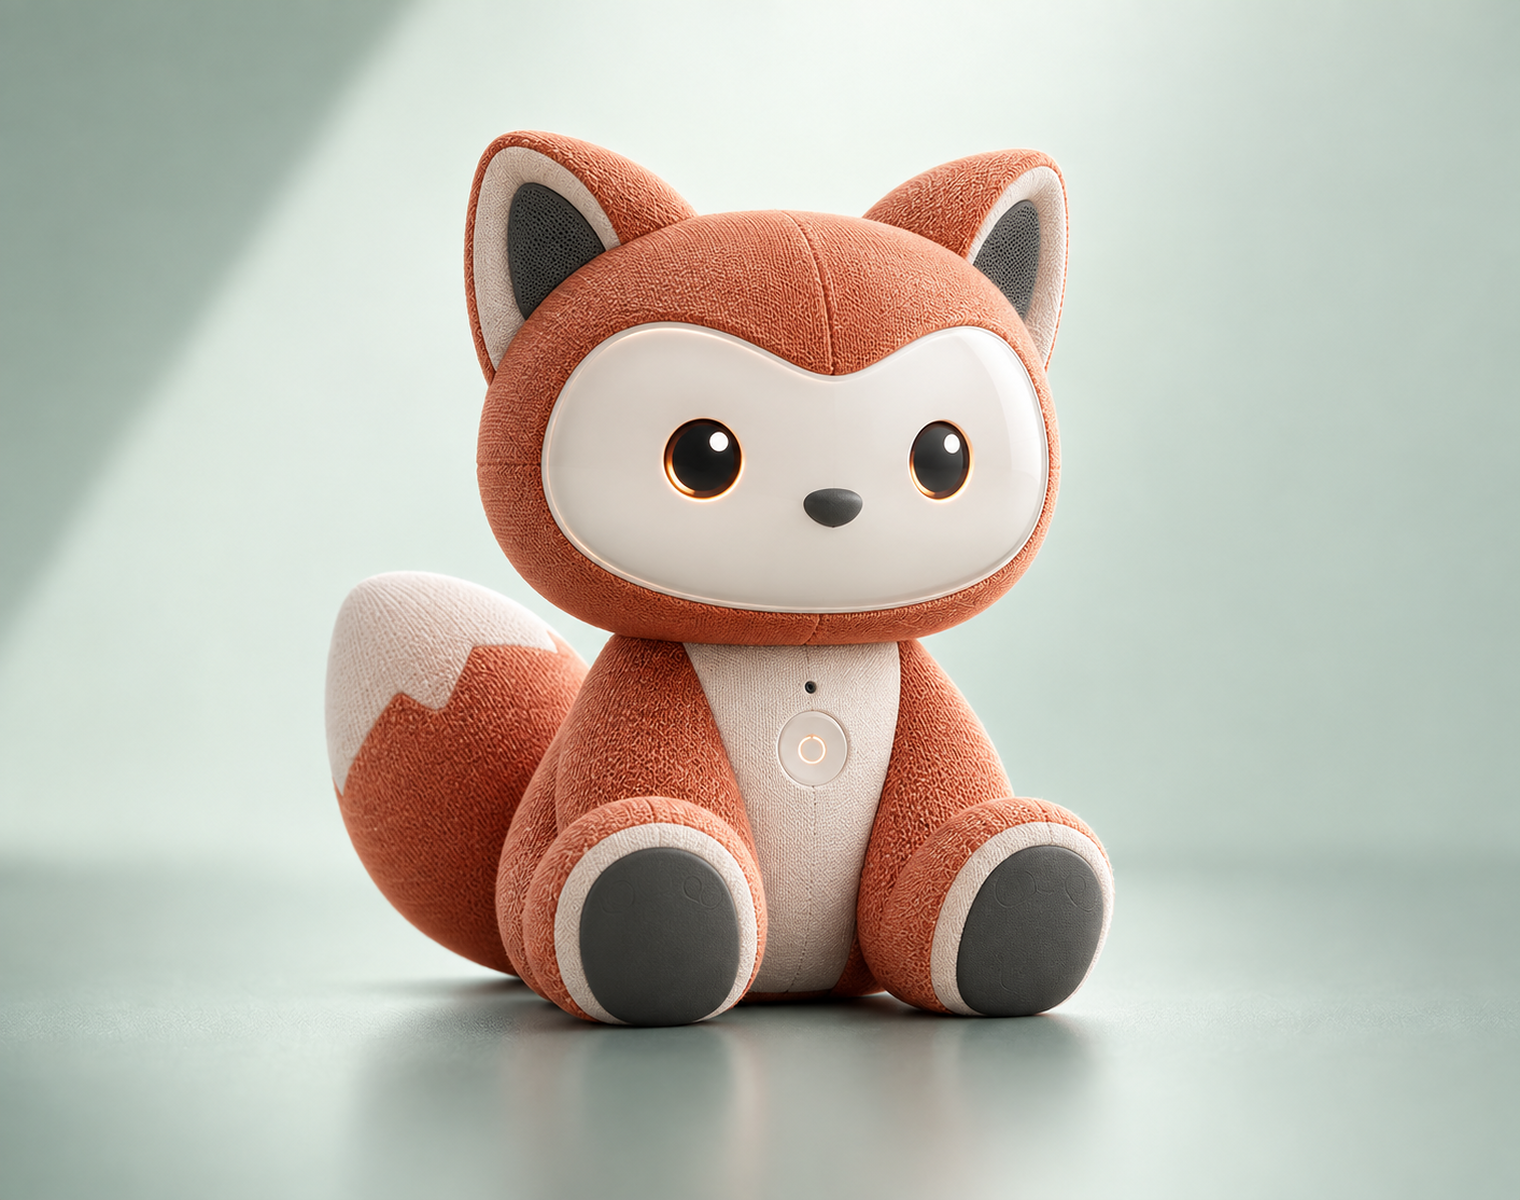
Unlimited access to advanced AI
Inference runs on the hardware you already ship, resulting in no per-use charges and no costs that scale with usage.

Runs on low-power hardware | Cloud-level intelligence | Works offline |No privacy risk | Zero token cost
 Explore our models
Inference runs on the hardware you already ship, resulting in no per-use charges and no costs that scale with usage.

Up to 3 GB of memory, bringing powerful AI to compact hardware from phones to consumer-grade boards.

Keep sensitive data secure with local processing that keeps data on your device.
Edge0 develops language and voice models for products ranging from high-performance systems to memory- and power-constrained devices.
Most stay at the research stage
A few reach high-compute hardware

A handful stop at mid-compute hardware


Default state: no stage gradient background shown.
Edge0 keeps the full 4-bit model on SSD and streams only the experts needed for each token into memory.
See the modelsEdge0-35B · sparse MoE
LFM2-2.6B
MiniCPM-V 4.0
Gemma 4 E2B
MiniCPM4-8B
Gemma 4 E4B
Qwen3.8-27B
Muse Glimmer 30B
Qen3.5-35B-A3B
DeepSeek-R1-Distill-Llama-70B
All models and specs
A 35-billion-parameter flagship on-device model that runs with 1–3 GB of memory and supports understanding and execution of complex tasks.
An 8-billion-parameter lightweight on-device model that runs with 1–2 GB of memory, suitable for Q&A and low-to-medium complexity tasks.
On the open-source ASR leaderboard — world-best 5.04% WER
0.6B size, 8B-grade voice — zero-shot cloning that captures the exact texture of your voice
//2026
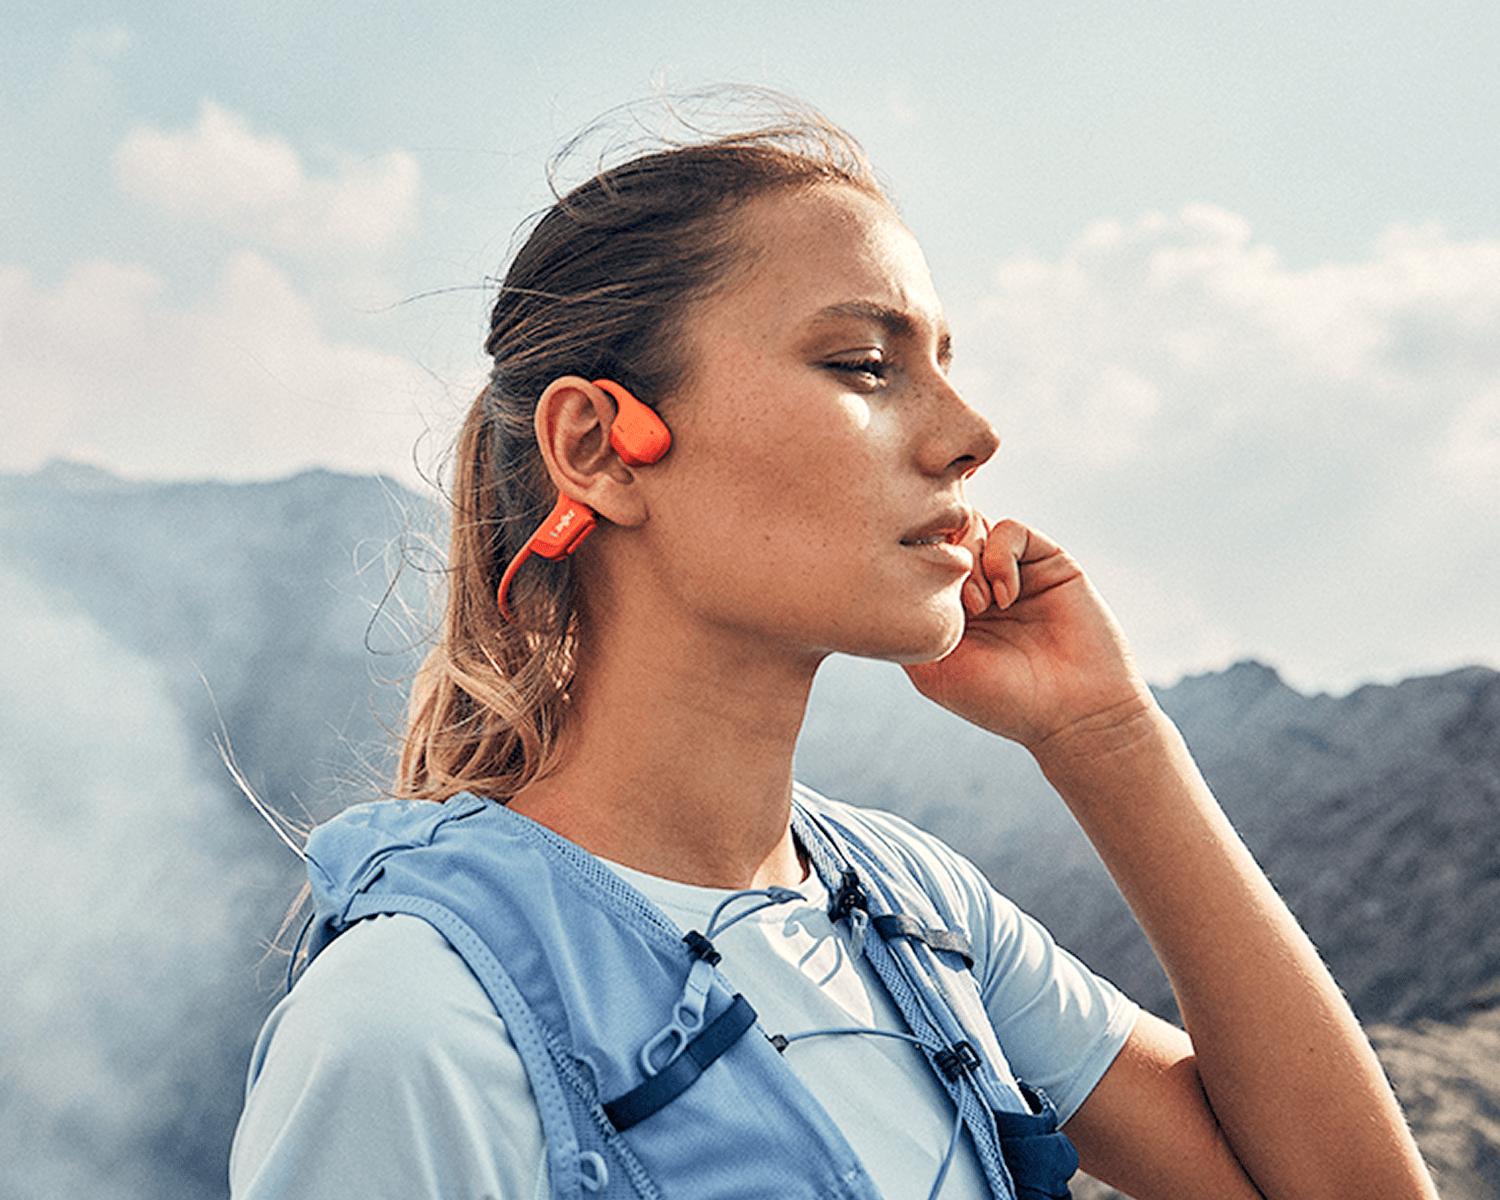
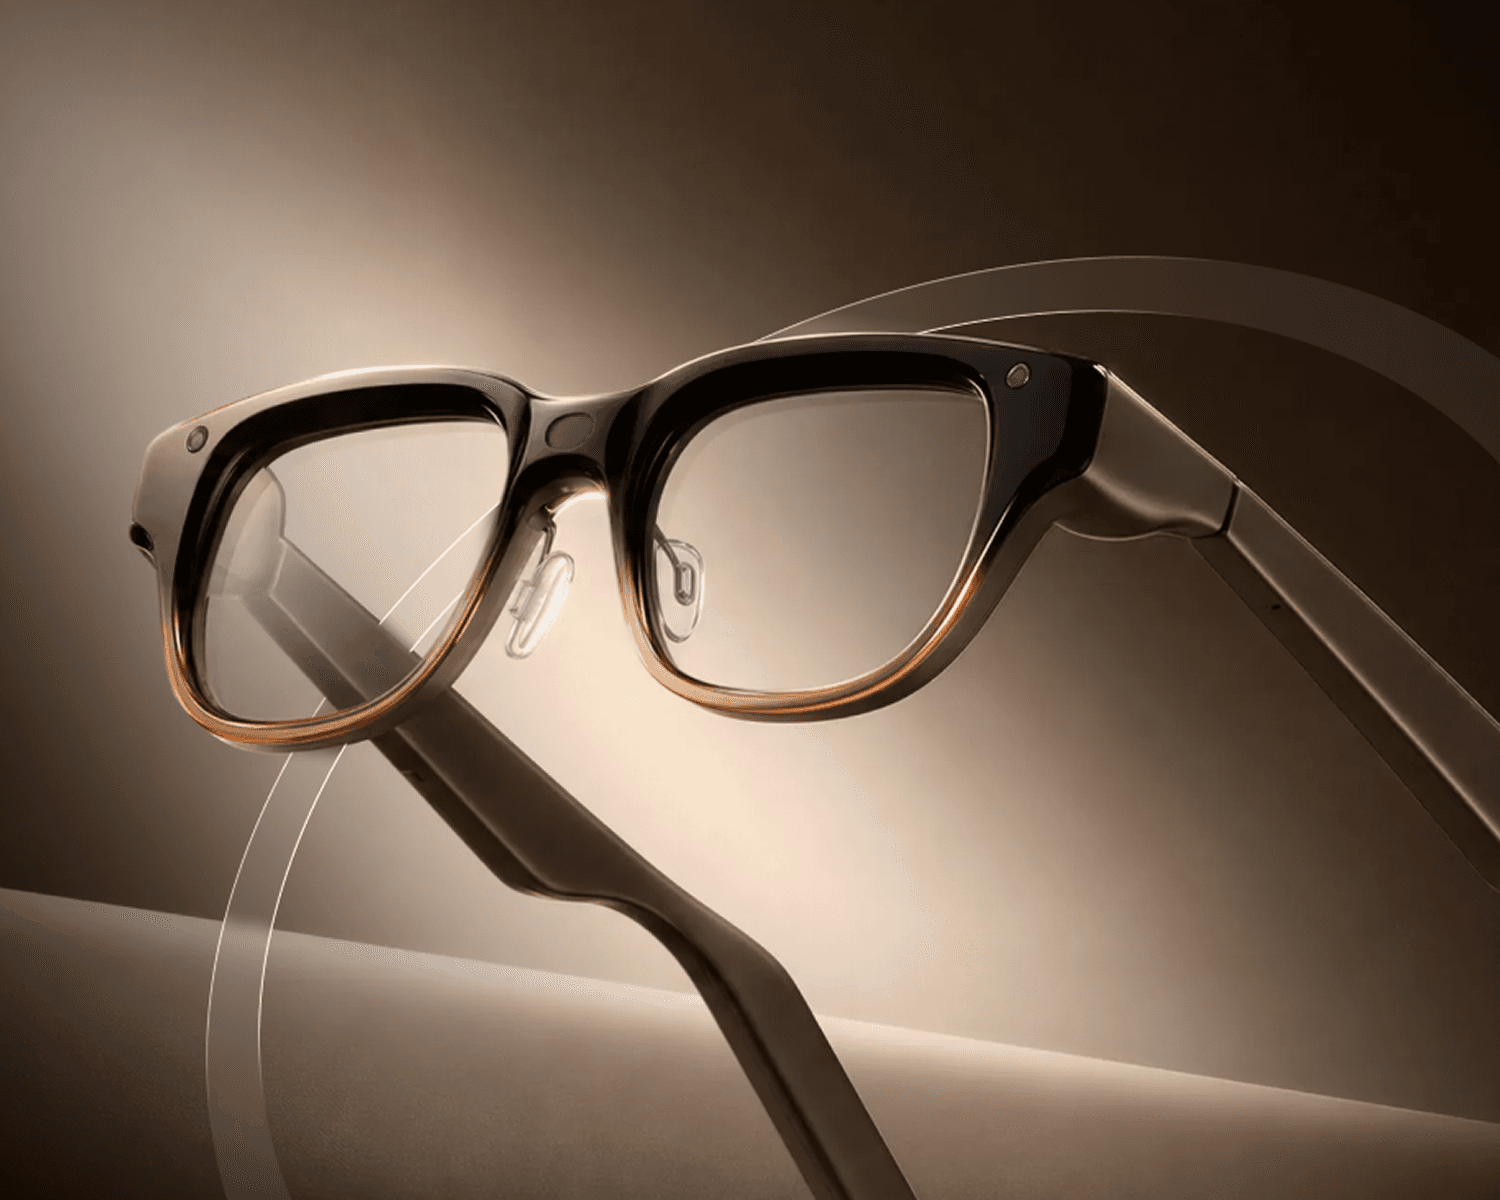
Edge-cloud voice SDK embeds in earbuds: natural commands, live readouts, zero hardware changes.

//2026
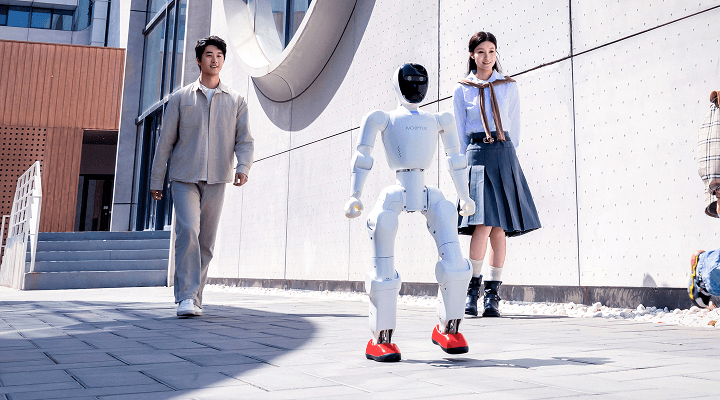
Edge-cloud HRI SDK embedded in humanoid robots — natural-language dialogue and command execution, fully functional offline or on weak networks.
//2026
Edge-cloud coordination cuts latency and cost: frequent commands on-device, complex tasks in cloud.
//2026
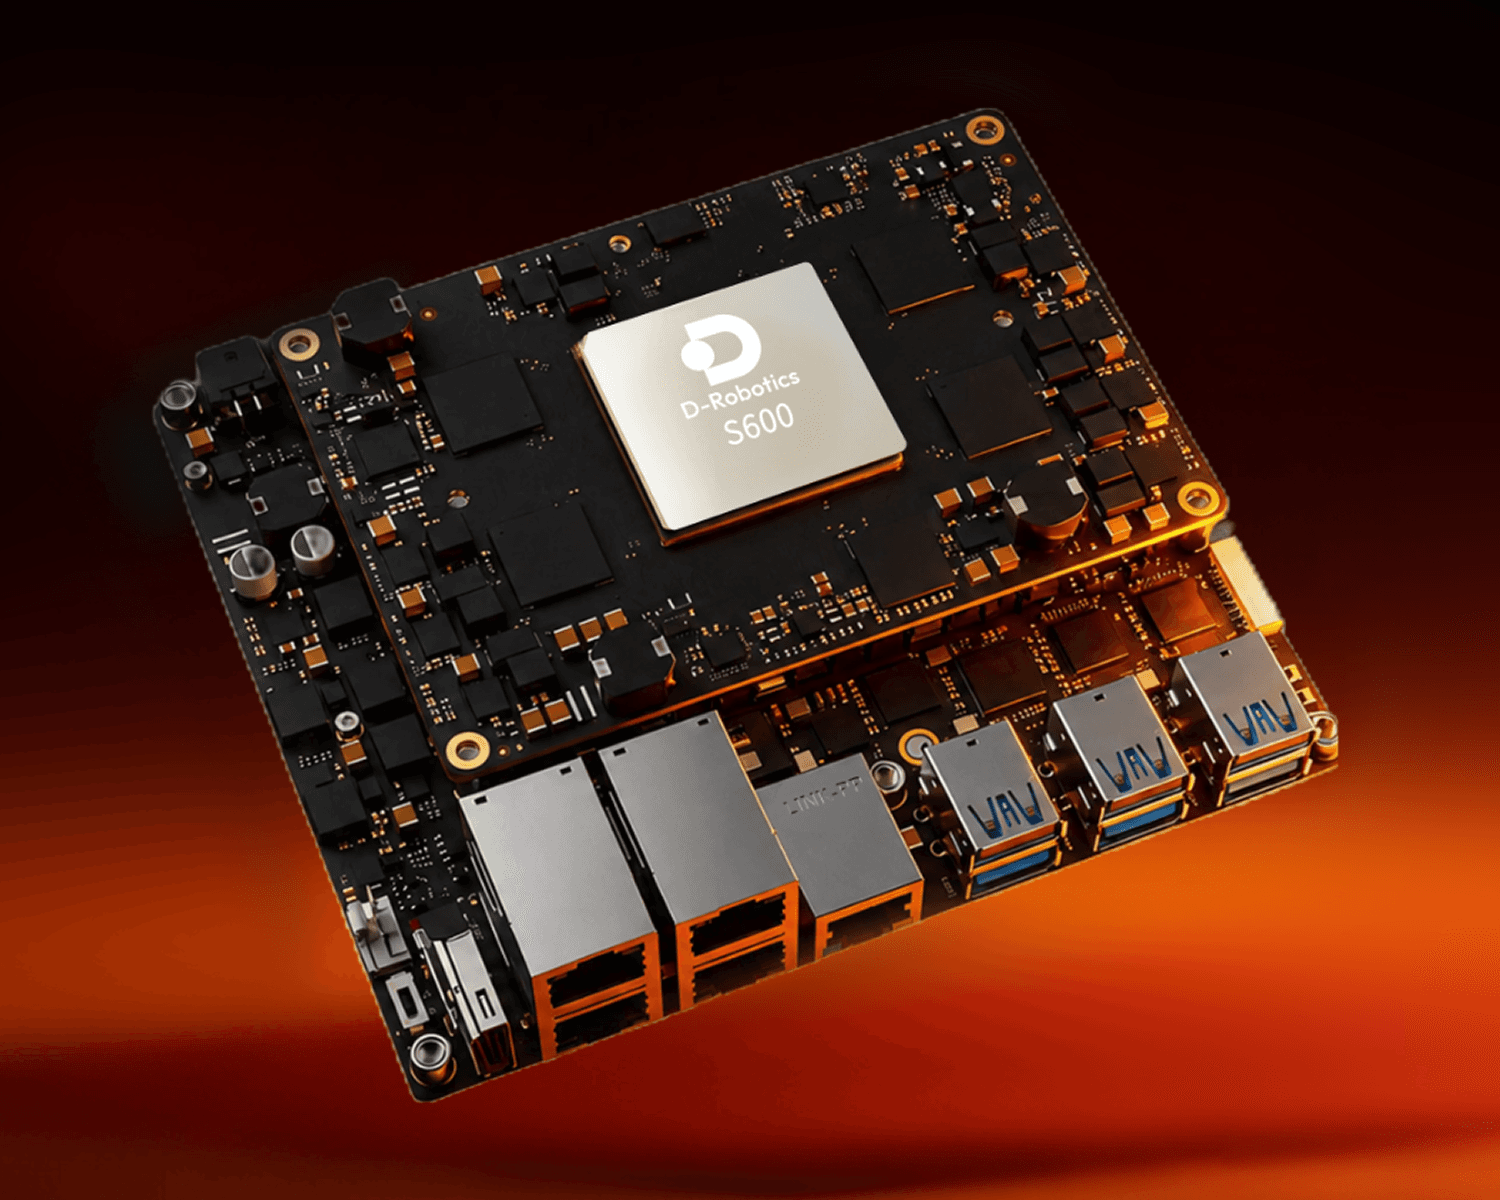
Robot chips plus edge voice models: out-of-the-box, offline, low-cost voice interaction for makers.
//2025
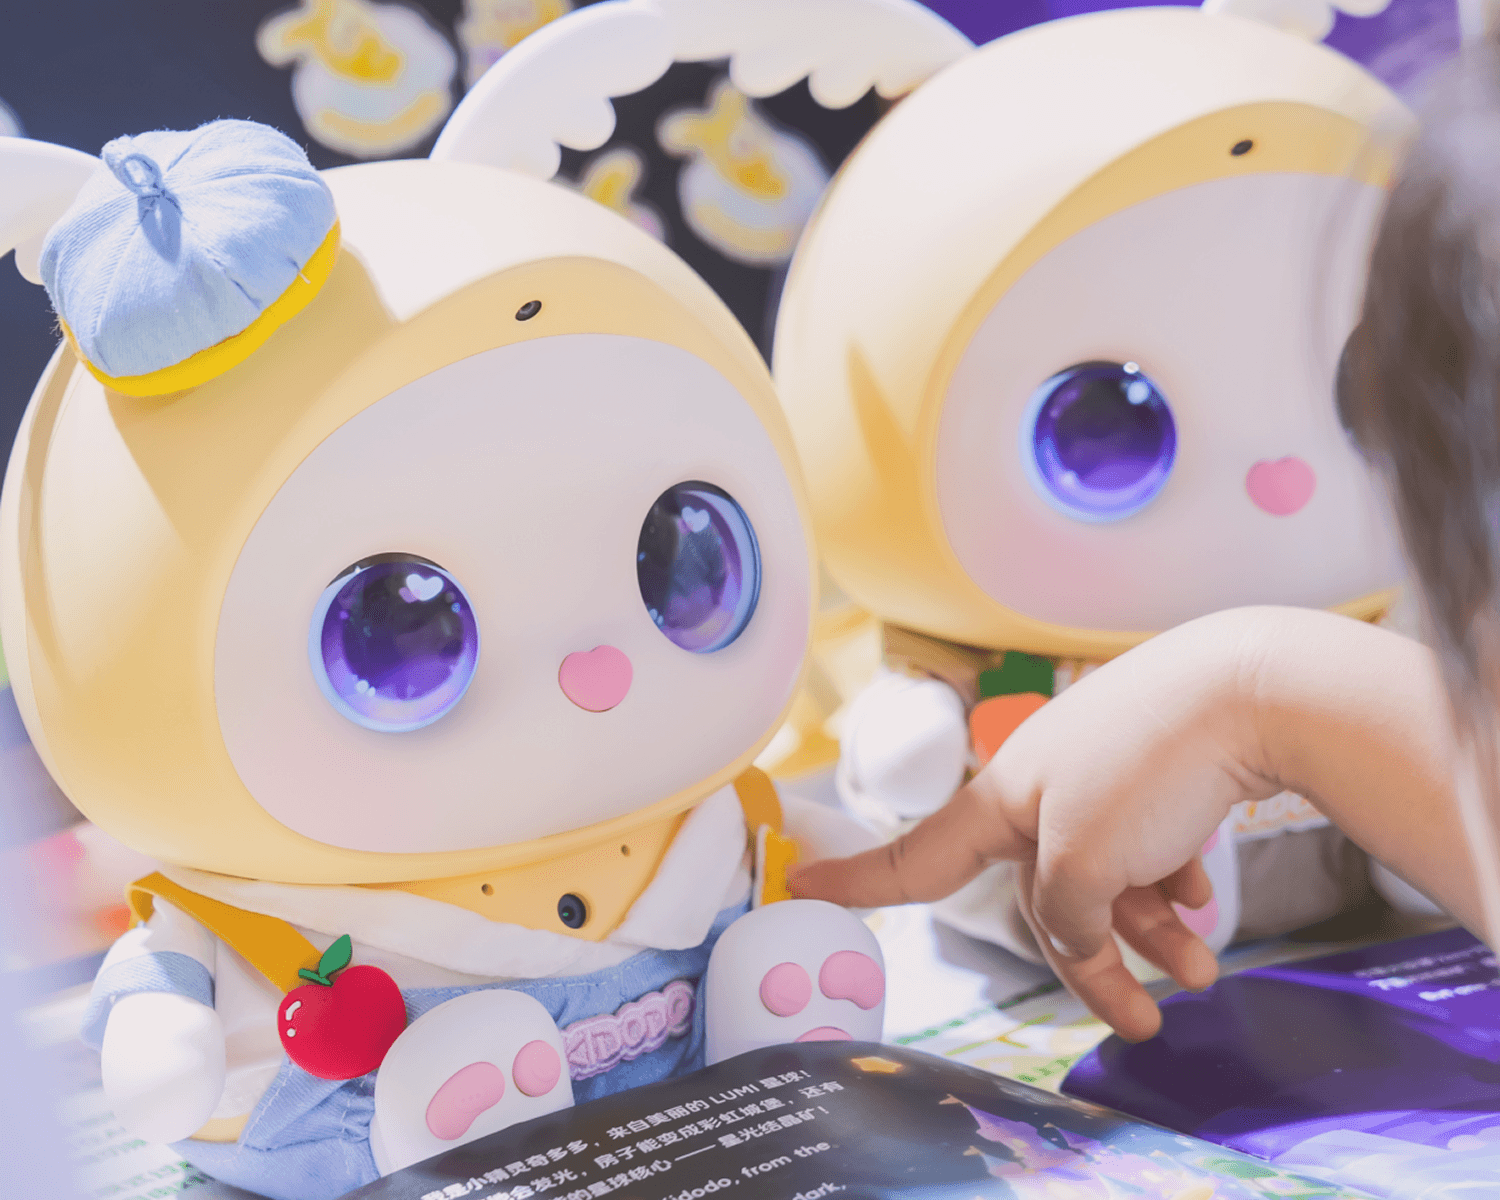
Edge-side models on a hybrid edge-cloud base answer fast commands and recognize emotion.
Inference happens on hardware you already shipped, so there is no token meter to run down and no bill that grows with usage.
The full model stays on SSD while the active working set is loaded into memory on demand.